Back to ProjectsAI / Machine Learning · 2025
Retrieval Augmented Generation
Multimodal AI Image Retrieval, Captioning & Narrative Generation
An AI-powered Image Retrieval RAG system combining CLIP, BLIP-2, Flan-T5, and Stable Diffusion for semantic image search, automatic captioning, and narrative generation.
My Role & Contributions
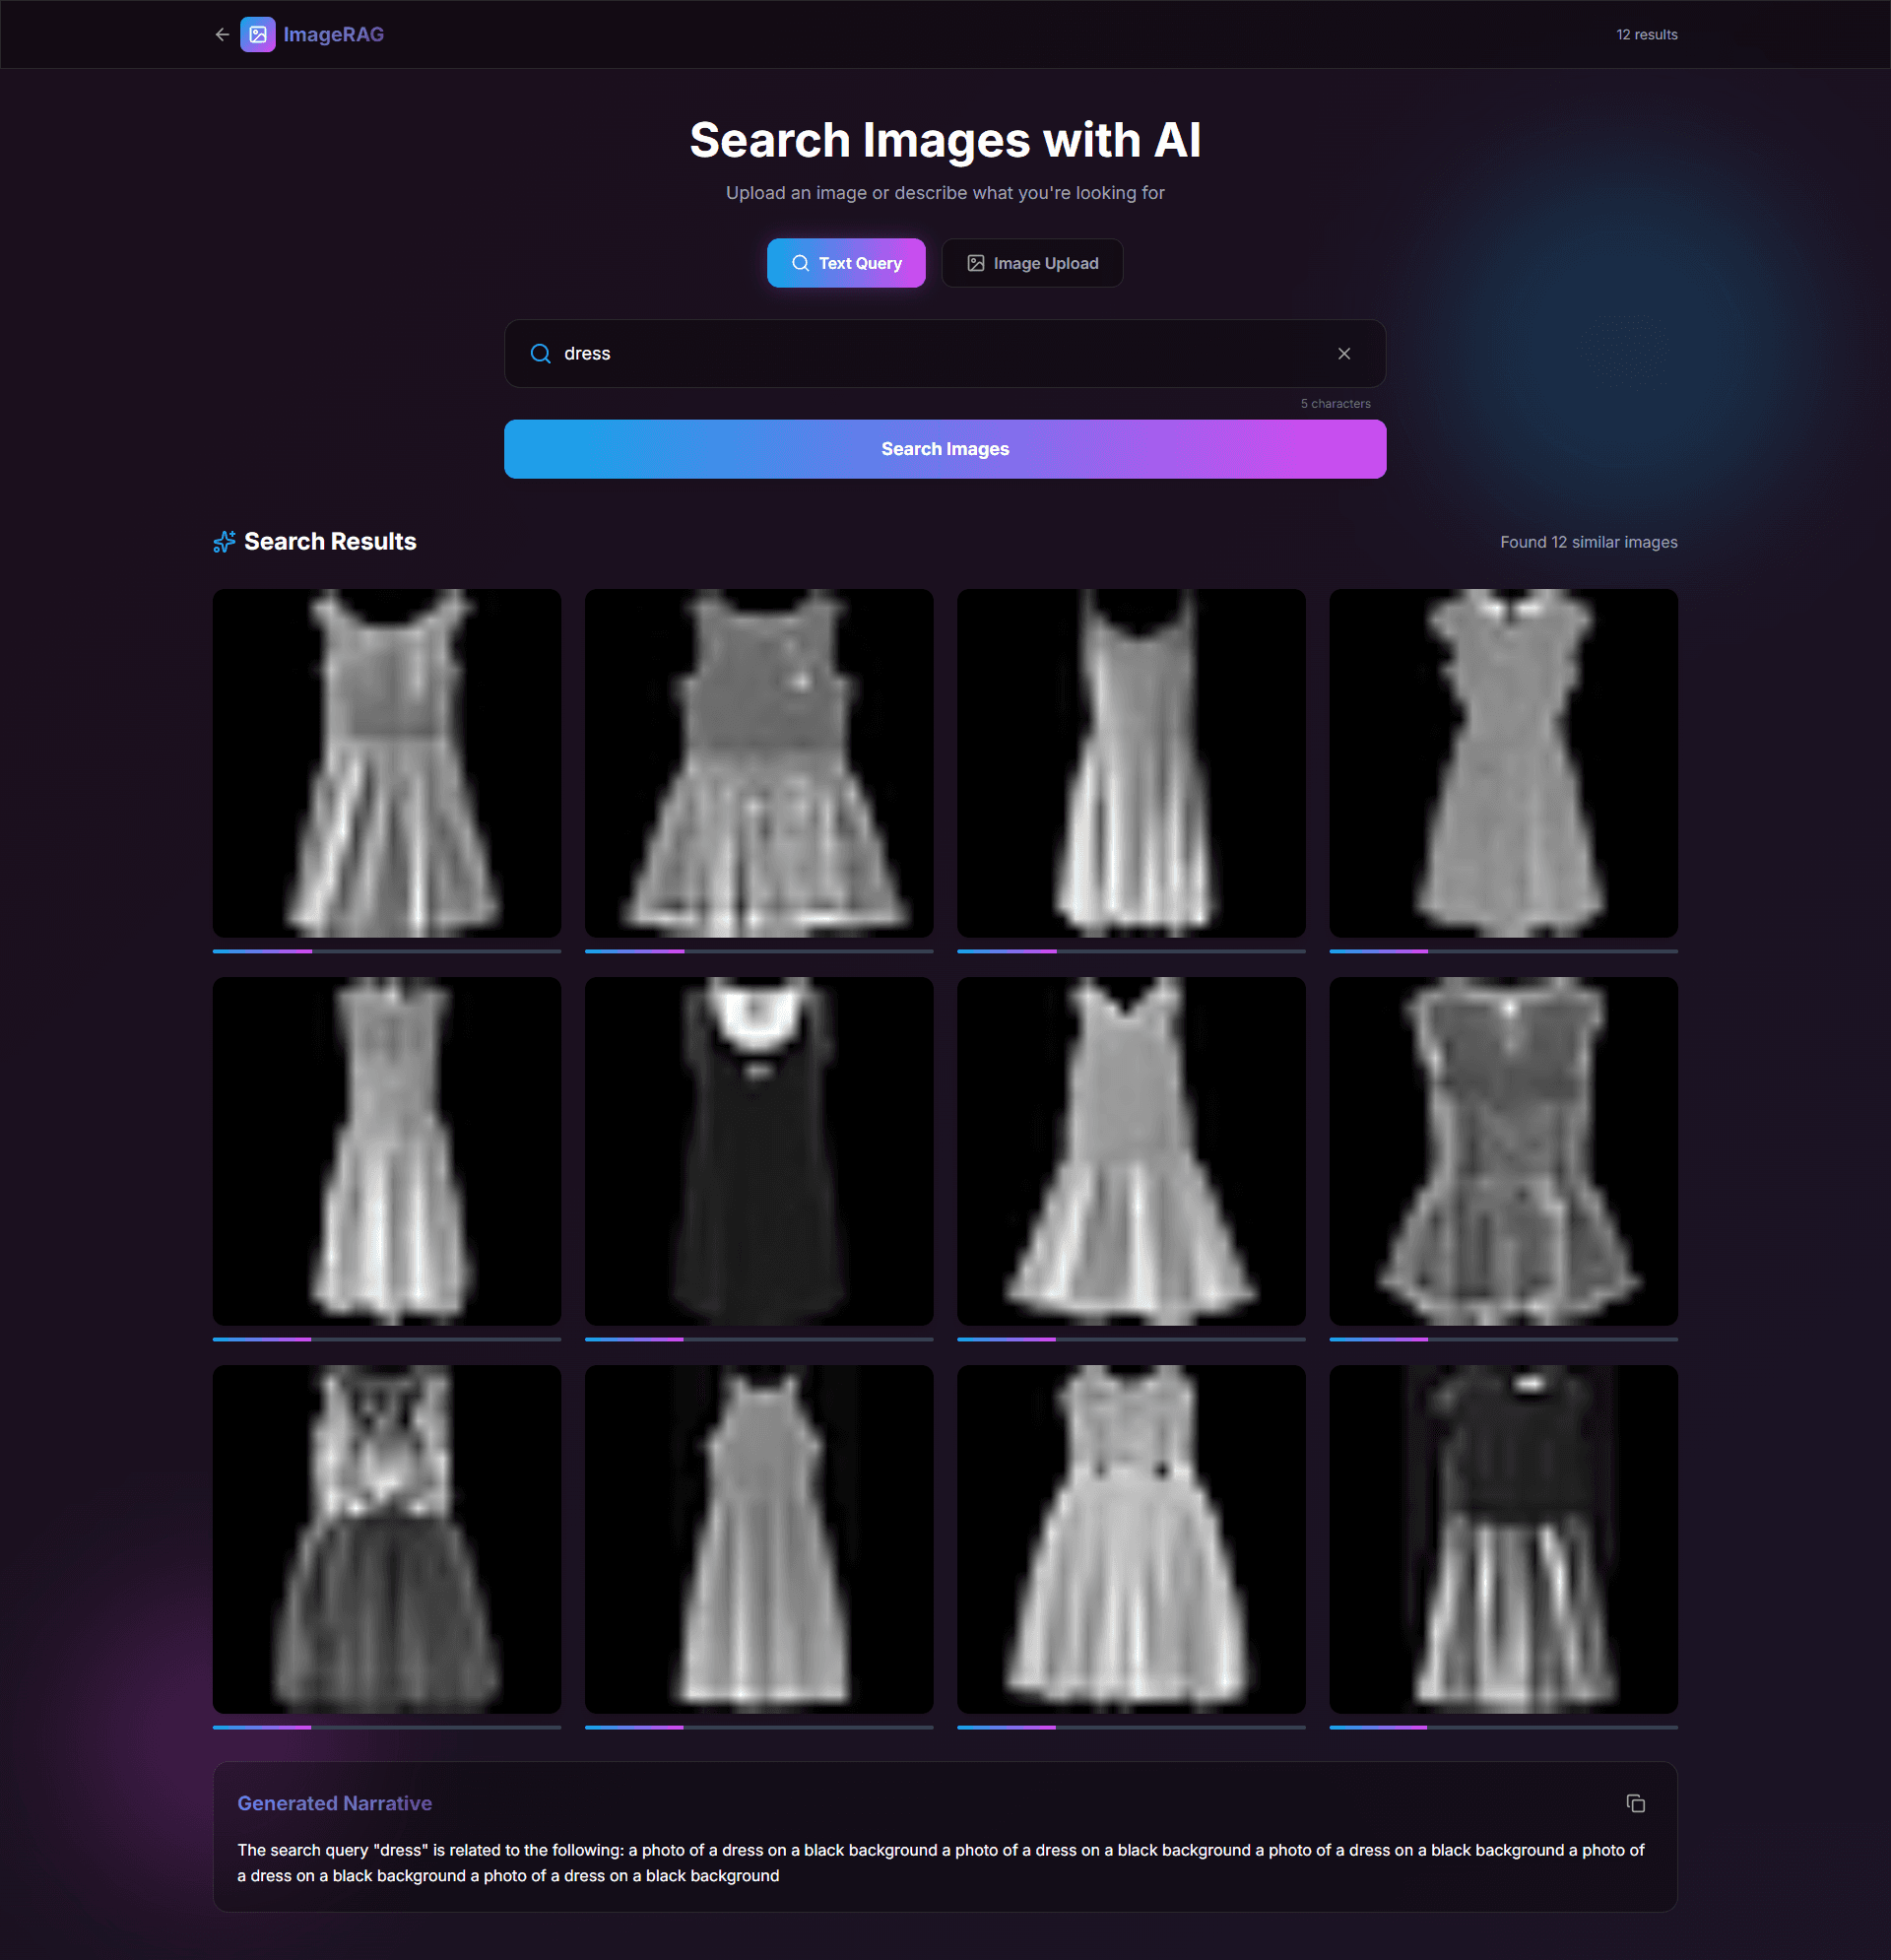
- 01Integrated OpenAI CLIP embeddings with a FAISS vector index for low-latency text-to-image and image-to-image retrieval.
- 02Built a multimodal RAG pipeline chaining BLIP-2 visual captioning with Flan-T5 for grounded narrative generation.
- 03Exposed the inference pipeline via an asynchronous FastAPI service with streaming responses.
Key Features
- 01CLIP-based semantic image search across large visual datasets
- 02BLIP-2 automatic image captioning with contextual descriptions
- 03Flan-T5 narrative generation grounded in retrieved visual context
- 04FAISS vector database for millisecond similarity search
- 05FastAPI backend with streaming response and async batch processing
Impact & Highlights
- Achieved sub-50ms top-k vector retrieval across thousands of indexed high-resolution images.
- Combined visual perception and LLM reasoning into a cohesive multimodal workflow.